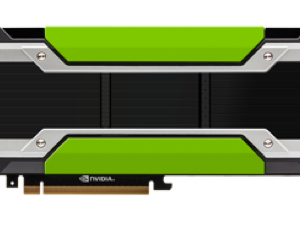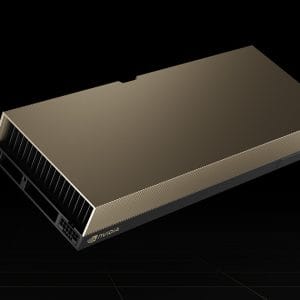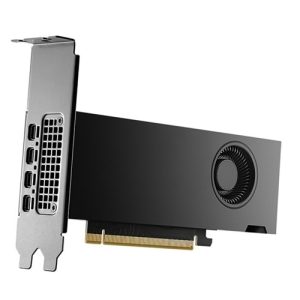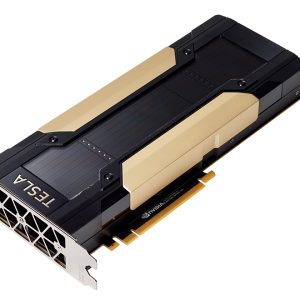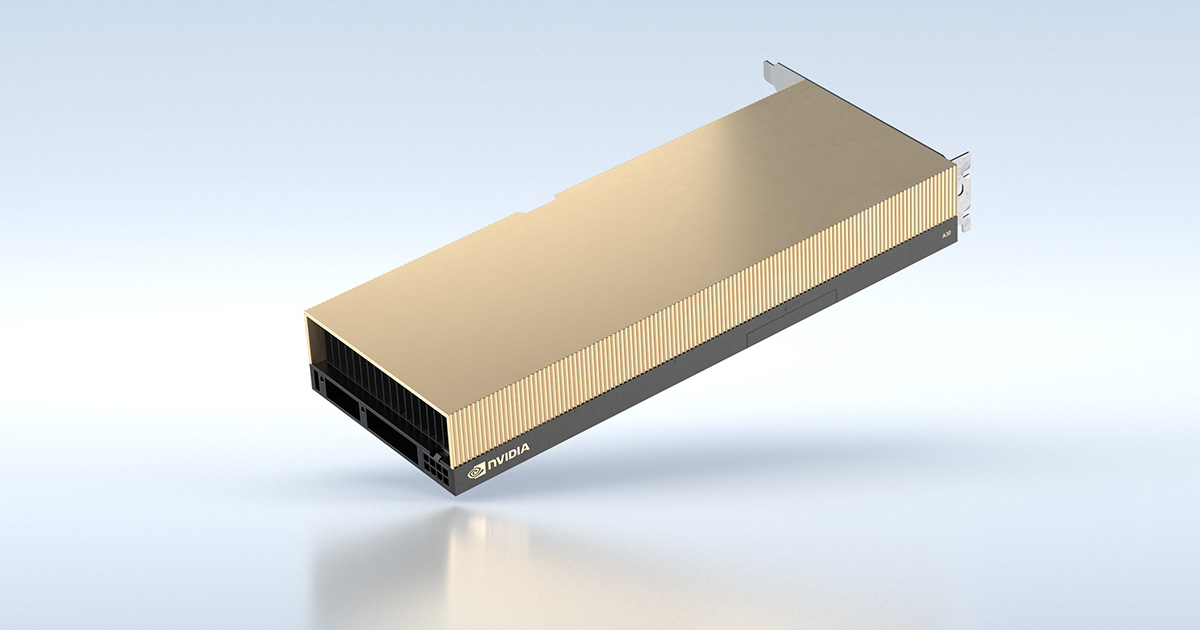
NVIDIA A30 เป็น Data Center GPU / Accelerator จาก NVIDIA เหมาะสำหรับงาน AI training, AI inference, HPC, virtual workstation รองรับการใช้งานระดับองค์กร ศูนย์ข้อมูล และงานวิจัยด้าน AI/HPC
การใช้งานที่เหมาะสม
- AI training
- AI inference
- HPC
- virtual workstation
ข้อมูลทางเทคนิค (Product Specifications)
| หัวข้อ | รายละเอียดสเปค |
| สถาปัตยกรรม GPU | NVIDIA Ampere |
| CUDA Cores | 3,804 |
| Tensor Cores (Gen 3) | 224 |
| ประสิทธิภาพ FP64 | 5.2 TFLOPS |
| FP64 เทนเซอร์คอร์ | 10.3 TFLOPS |
| FP32 | 10.3 TFLOPS |
| TF32 เทนเซอร์คอร์ | 82 TFLOPS (165 TFLOPS with sparsity) |
| BFLOAT16 / FP16 (Tensor) | 165 TFLOPS (330 TFLOPS with sparsity) |
| INT8 (Tensor) | 330 TOPS (661 TOPS with sparsity) |
| INT4 (Tensor) | 661 TOPS (1,321 TOPS with sparsity) |
| หน่วยความจํา GPU | 24 GB HBM2 (ECC) |
| แบนด์วิดท์หน่วยความจํา | 933 GB/s |
| การเชื่อมต่อระบบ | PCIe Gen4 ×16 (64 GB/s), รองรับ NVLink (200 GB/s, optional) |
| MIG Support | Up to 4 instances (6 GB each, 12 GB each, or full 24 GB) |
| vGPU Support | Yes (eg. NVIDIA AI Enterprise, vCS) |
| ระบบระบายความร้อน | Passive |
| กําลังไฟสูงสุด (TDP) | 165 W |
| Form Factor | Dual-slot, full-height, full-length PCIe card |
| Media Engines | 1 optical flow accelerator (OFA), 1 JPEG decoder (NVJPEG), 4 video decoders (NVDEC) |
| ECC Memory | Yes |
| Technical detail | NVIDIA Ampere GPU architecture |
| Technical detail | 24GB HBM2 Memory |
| Max. Power Consumption | 165W |
| Interconnect Bus | PCIe Gen. 4: 64GB/s 3rd NVLink: 200GB/s |
| Multi-instance GPU (MIG) | 4 GPU instances @ 6GB each 2 GPU instances @ 12GB each 1 GPU instance @ 24GB |
| Technical detail | Virtual GPU (vGPU) software support |
| Technical detail | NVIDIA A30 คือการ์ด GPU สําหรับศูนย์ข้อมูลที่วางตําแหน่งในหมวด mainstream enterprise servers โดยใช้สถาปัตยกรรม Ampere ที่ทรงพลัง พร้อม Tensor Core รุ่นที่สามและระบบ Multi‐Instance GPU (MIG) ที่ช่วยแบ่งการ์ดออกเป็นหลายส่วนเพื่อรองรับการใช้งานพร้อมกันอย่างมีประสิทธิภาพ เหมาะอย่างยิ่งสําหรับงานฝึกโมเดล AI, การประมวลผลประสิทธิภาพสูง (HPC) และการใช้งาน AI inference ขนาดใหญ่ที่ต้องการความทนทานและประสิทธิภาพสูงในสภาพแวดล้อมการทํางานเชิงองค์กร |
| Technical detail | NVIDIA A30 ประกอบด้วย 3,804 CUDA Cores และ 224 Tensor Cores รุ่นที่ 3 รองรับหลายความแม่นยําทางคณิตศาสตร์ เช่น FP64, TF32, FP16, BFLOAT16, INT8 และ INT4 โดยให้ประสิทธิภาพสูงสุดใน Tensor Core (เช่น TF32 สูงถึง 165 TFLOPS กับ sparsity) มาพร้อมหน่วยความจํา HBM2 ขนาด 24 GB แบนด์วิดท์ถึง 933 GB/s รองรับ MIG แยกการ์ดเป็น 4 ส่วน ระบบระบายความร้อนแบบ passive ใช้พลังงานสูงสุดเพียง 165 W พร้อม PCIe Gen4 และรองรับ NVLink สําหรับการสื่อสารระหว่าง GPU ต่อยอดประสิทธิภาพงานหนักในศูนย์ข้อมูล |
| Technical detail | The NVIDIA A30 is a data-center GPU targeted at mainstream enterprise servers. Built on the Ampere architecture with third-generation Tensor Cores and Multi‐Instance GPU (MIG) capabilities, it enables simultaneous, isolated workloads on a single card. It is ideal for AI training, high-performance computing (HPC), and large-scale AI inference tasks requiring reliability, performance, and efficient resource utilization. |
| Technical detail | The NVIDIA A30 features 3,804 CUDA Cores and 224 third-generation Tensor Cores, supporting various numeric precisions including FP64, TF32, FP16, BFLOAT16, INT8, and INT4. It delivers high Tensor Core performance (e.g., TF32 up to 165 TFLOPS with sparsity) and includes 24 GB of HBM2 memory with 933 GB/s bandwidth. It supports MIG (up to four isolated instances), passive cooling, up to 165 W power draw, PCIe Gen4 interface, and optional NVLink connectivity for multi-GPU communication—making it an efficient and versatile choice for enterprise-scale AI and HPC workloads |
| Technical detail | The NVIDIA A30 is a versatile data-center GPU that delivers both AI and high-performance compute capabilities in a compact, efficient package. Equipped with third-gen Tensor Cores handling everything from FP64 to INT4, and MIG for partitioned, multi-tenant workloads, it maximizes resource usage. Its passive cooling, low 165 W power draw, and fast connectivity via PCIe Gen4 and optional NVLink make it a cost-efficient, high-performance solution for organizations accelerating AI, HPC, or inference workflows. |
| Technical detail | Condition & Warranty |
| Technical detail | ✔ Fully tested and 100% working ✔ Secure packaging for safe shipping ✔ Warranty available (subject to store policy) |
ข้อมูลอ้างอิงจากผู้ผลิต: NVIDIA
สนใจสอบถามราคา สเปค หรือขอใบเสนอราคา ติดต่อได้ที่ LINE: @metaxr