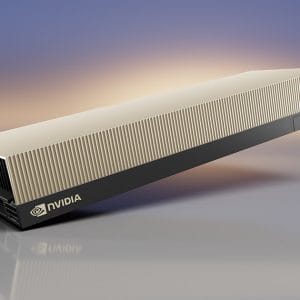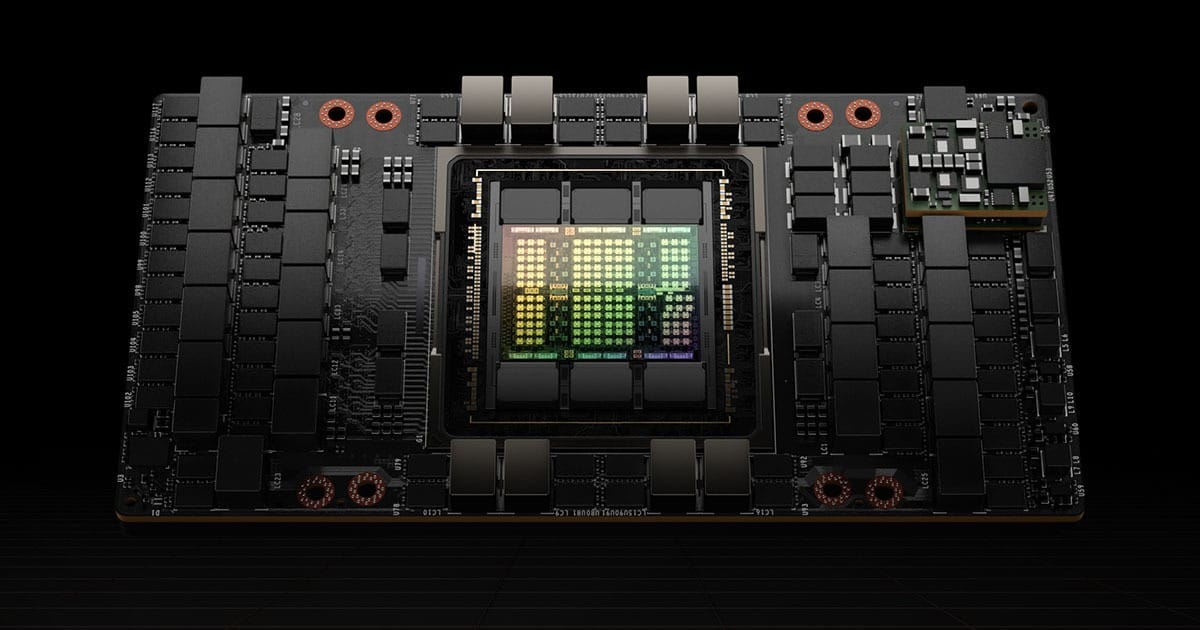
NVIDIA H100 เป็น Data Center GPU / Accelerator จาก NVIDIA เหมาะสำหรับงาน AI training, AI inference, HPC, virtual workstation รองรับการใช้งานระดับองค์กร ศูนย์ข้อมูล และงานวิจัยด้าน AI/HPC
คำอธิบายจากผู้ผลิต: A Massive Leap in Accelerated Compute.
การใช้งานที่เหมาะสม
- AI training
- AI inference
- HPC
- virtual workstation
ข้อมูลทางเทคนิค (Product Specifications)
| 부분 | รายละเอียดสเปค |
| สถาปัตยกรรม GPU | NVIDIA Hopper architecture |
| Variant | H100 SXM / H100 NVL (PCIe) |
| FP64 (Precise) | SXM: 34 TFLOPS / NVL: 30 TFLOPS |
| FP64 Tensor Core | SXM: 67 TFLOPS / NVL: 60 TFLOPS |
| FP32 | SXM: 67 TFLOPS / NVL: 60 TFLOPS |
| TF32 Tensor Core | SXM: 989 TFLOPS / NVL: 835 TFLOPS |
| BF16 Tensor Core | SXM: 1,979 TFLOPS / NVL: 1,671 TFLOPS |
| FP16 Tensor Core | SXM: 1,979 TFLOPS / NVL: 1,671 TFLOPS |
| FP8 Tensor Core | SXM: 3,958 TFLOPS / NVL: 3,341 TFLOPS |
| INT8 TOPS | SXM: 3,958 / NVL: 3,341 |
| GPU Memory | SXM: 80 GB / NVL: 94 GB |
| 메모리 대역폭 | SXM: 3.35 TB/s / NVL: 3.9 TB/s |
| TDP (ความร้อนสูงสุด) | SXM: up to 700 W / NVL: 350–400 W |
| Multi‐Instance GPU (MIG) | Up to 7 MIGs (10 GB each SXM, 12 GB each NVL) |
| Form Factor | SXM / PCIe dual-slot air-cooled |
| Interconnect | NVLink: 900 GB/s (SXM) or 600 GB/s (NVL); PCIe Gen5: 128 GB/s |
| Transformer Engine & DPX | เร่ง LLM training/inference และ dynamic programming ได้เร็ว 30×, 7× |
| จํานวน CUDA cores (PCIe) | 14,592 CUDA cores |
| Transistors & Process | 80 billion transistors on TSMC 4N process |
| L2 Cache | 50 MB |
| Asynchronous architecture | รองรับ tensor memory accelerator, shared memory communications |
| Technical detail | NVIDIA Hopper GPU architecture |
| Technical detail | 80GB Memory |
| Max. Power Consumption | 300W~350W (configurable) |
| Interconnect Bus | PCIe Gen. 5: 128GB/s NVLink: 600GB/s |
| Multi-instance GPU (MIG) | 7 GPU instances @ 10GB each |
| Technical detail | NVIDIA H100 คือ GPU ศูนย์ข้อมูลที่ใช้สถาปัตยกรรม Hopper อันทันสมัย ถูกออกแบบเพื่อรองรับงาน AI, HPC, และการวิเคราะห์ข้อมูลอย่างเต็มรูปแบบ โดยมี Tensor Cores รุ่นที่ 4, หน่วยความจํา HBM3 และการเชื่อมต่อที่เหนือชั้น ช่วยเร่งฝึกและประมวลผลโมเดลขนาดใหญ่และงานประมวลผลเชิงวิทยาศาสตร์ได้อย่างมีประสิทธิภาพสูงสุด |
| Technical detail | NVIDIA H100 มีให้เลือกสองเวอร์ชันคือ SXM (เพิ่มประสิทธิภาพสูงสุด) และ PCIe (ใช้งานทั่วไป) ประสิทธิภาพสูงสุดถึง ~4 พัน TFLOPS ใน FP8, รองรับ MIG (Multi‐Instance GPU) แบ่งการ์ดเป็นหลายหน่วย, ใช้ PCIe Gen5, NVLink ความเร็วสูง และมีหน่วยความจํา HBM3 ขนาด 80 GB พร้อมแบนด์วิดท์สูงถึง 3.35 TB/s (SXM) หรือ 3.9 TB/s (NVL) เหมาะกับระบบระดับองค์กรที่มีความต้องการประมวลผลสูง |
| Technical detail | The NVIDIA H100 is a data‐center GPU built on the advanced Hopper architecture, engineered for full-scale AI, HPC, and data analytics workloads. Featuring 4th‐generation Tensor Cores, HBM3 memory, and high-speed interconnects, it accelerates training and inference of large models and scientific compute tasks with exceptional performance. |
| The NVIDIA H100 is available in two variants | SXM for maximum performance and PCIe for broader compatibility. It offers up to ~4,000 TFLOPS (FP8) peak performance, supports MIG for instance partitioning, and features PCIe Gen5 and high-speed NVLink. With 80 GB of HBM3 memory delivering up to 3.35 TB/s (SXM) or 3.9 TB/s (NVL) bandwidth, it’s ideal for enterprise-level compute-intensive tasks. |
| Technical detail | The NVIDIA H100 stands as a pinnacle of data-center GPUs, powered by the Hopper architecture. Its Transformer Engine and 4th-gen Tensor Cores dramatically accelerate AI model training and inference, especially for LLMs and scientific compute. With MIG for workload partitioning, vast HBM3 memory, and high-speed interconnects like NVLink, the H100 delivers an exponential leap in performance. It’s the go-to choice for enterprises pushing towards exascale AI compute—combining power, flexibility, and robust security. |
| Technical detail | Condition & Warranty |
| Technical detail | ✔ Fully tested and 100% working ✔ Secure packaging for safe shipping ✔ Warranty available (subject to store policy) |
ข้อมูลอ้างอิงจากผู้ผลิต: NVIDIA
สนใจสอบถามราคา สเปค หรือขอใบเสนอราคา ติดต่อได้ที่ LINE: @metaxr